Probabilities
ProvSQL computes the probability that a query answer holds in a
probabilistic database [Green and Tannen, 2006]: a database in
which every input provenance token carries an independent probability of
being present, from which ProvSQL derives the marginal probability of
each query answer. Beyond independent inputs it also models
correlated inputs – block-independent databases through
repair_key – and a continuous tier, where columns of type
random_variable carry distributions rather than scalars.
This chapter starts with the everyday workflow – assigning input probabilities, evaluating a query, aggregates – and then turns to reference material: when exact evaluation is tractable, the specialised compilers for hard queries, the explicit method catalogue, and the performance optimisations.
Setting input probabilities
Assign a probability to each input tuple’s provenance token using
set_prob:
SELECT set_prob(provenance(), 0.8) FROM mytable WHERE id = 1;
Or in bulk, from a column of the table itself:
SELECT set_prob(provenance(), reliability) FROM sightings;
Probabilities must be in the range [0, 1].
A probability is written once: set_prob writes one on a
token that has none, accepts the identical value again, and refuses a
different one. To give a tuple a different probability, give it a
different input gate:
UPDATE sightings SET provsql = provsql.replace_input(provsql, 0.3)
  WHERE id = 42;
Results already derived keep the old probability; Persistence, backups and replication
covers this and the block form replace_block for
repair_key tables.
To read back a stored probability with get_prob:
SELECT get_prob(provenance()) FROM mytable;
get_prob returns 1 both for a token set as certain and for
one with no probability; probability_is_set tells them apart.
Computing query probabilities
Use probability_evaluate to evaluate the probability that a
query result holds, given the assigned input probabilities:
SELECT person,
       probability_evaluate(provenance()) AS prob
FROM suspects;
probability is a short alias with the same arguments, to match
the concise expected / variance / support
surface. It also accepts a Boolean event directly –
probability(x > y) over random_variable columns, or
probability(1 > 0) on a deterministic event (total: 1 if it holds,
0 otherwise) – see the comparison-event surface in
Continuous Distributions.
With no further argument it returns the exact probability. An
optional second argument names a computation method and a third passes
method-specific parameters (a comma-separated key=value list whose
keys depend on the method; a bare sample count or a delta;epsilon pair
is also accepted). You rarely
need them: see Choosing a guarantee just
below, and the full catalogue under Forcing a specific method.
ProvSQL Studio’s evaluation strip
exposes probability_evaluate interactively, with method and
argument selectors.
Choosing a guarantee, not a method
In practice you do not pick a method. Ask for the guarantee you want and let ProvSQL choose how to compute it:
exact – the default:
probability_evaluate(provenance())returns the true probability.relative
(ε, δ)–probability_evaluate(provenance(), 'relative', 'epsilon=0.05,delta=0.01'): the estimate is within a factor1 ± εof the true value with probability1 − δ. The right choice for rare events (small probabilities), where an absolute error bound would be meaningless.additive
(ε, δ)–probability_evaluate(provenance(), 'additive', 'epsilon=0.05,delta=0.01'): the estimate is withinεof the true value (absolute) with probability1 − δ.
A cost-based chooser then picks and runs the cheapest method that meets your request, per query. Three things make this safe to rely on:
The tolerances nest (exact ⊂ relative ⊂ additive), so a
relativeoradditiverequest still returns the exact value whenever an exact method is cheapest (“exact when cheaper”) – you never pay for approximation you did not need.The cost of a few methods is hard to predict from the circuit alone, so the chooser runs each optimistic pick under a budget and escalates automatically if it turns out slow – a pathological circuit never hangs on the wrong method.
A
δ = 0(no-failure) approximate request is honoured by a deterministic method, not a sampler.
Naming a method explicitly forces a specific algorithm: useful for
EXPLAIN-style understanding, or in the rare case where you know your
circuits better than the cost model. The full catalogue,
with a summary table of where each method shines, is under
Forcing a specific method; most users can skip it.
Quick bounds without exact evaluation
When only a coarse estimate is needed, probability_bounds
returns cheap lower and upper bounds on the marginal probability of a
monotone-DNF token (as OUT parameters lower / upper),
without the cost of exact compilation:
SELECT person, (probability_bounds(provenance())).*
FROM suspects;
Aggregates: expected values and HAVING
Expected values of aggregates
For aggregate queries over a probabilistic table, expected
computes the expected value of a COUNT, SUM, MIN, MAX or
AVG result:
SELECT dept,
       expected(COUNT(*)) AS expected_count,
       expected(SUM(salary)) AS expected_salary
FROM employees
GROUP BY dept;
The expectation is over the possible worlds in which the value exists,
i.e., where its group has a row; it is NULL only if the value never
exists. A COUNT without GROUP BY exists in every world, and is
0 where no row is present. The result is exact for AVG over
tuple-independent rows and for any aggregate depending on at most 20
input tuples; otherwise it is estimated by Monte Carlo at the
provsql.rv_mc_samples budget.
An optional second argument gives the conditional expectation
E[aggregate | condition], for a provenance condition; it is the
aggregate-specific spelling of the conditioning operator | (see
Conditioning).
HAVING with probabilities
HAVING clauses are supported in the probabilistic setting.
The following aggregate functions in HAVING are handled:
COUNT, SUM, AVG, MIN, MAX:
SELECT dept, probability_evaluate(provenance())
FROM employees
GROUP BY dept
HAVING COUNT(*) > 2;
Arithmetic over these aggregates in HAVING (including comparisons
between two aggregates and integer-division thresholds) is also handled;
see the aggregation chapter for the supported forms
and their semantics. For the common COUNT / MIN / MAX /
SUM thresholds a closed-form shortcut keeps the exact call fast; see
HAVING closed-form shortcuts.
A SUM (or the AVG that reduces to one) whose possible values
span a very large range cannot be evaluated exactly in reasonable time (the
problem is pseudo-polynomial: exact cost grows with the magnitude of the
values; MIN and MAX have a magnitude-independent closed form and are
not affected). In that case ask for an approximate answer instead – a
relative or additive guarantee:
SELECT probability_evaluate(provenance(), 'relative', 'epsilon=0.05,delta=0.01')
FROM orders GROUP BY region HAVING sum(amount_cents) > 100000000;
Continuous random variables
The discrete-Bernoulli setting above can be combined with a
continuous tier: columns of type random_variable carry
distributions (Normal, Uniform, Exponential, Erlang, Gamma, Log-normal, Weibull, Pareto, Beta, Categorical,
Mixture) rather than scalars, and WHERE predicates on these
columns become conditioning events on the row’s provenance.
Evaluation uses Monte Carlo by default and analytical closed forms
where they apply (e.g., comparisons decidable from the supports, exact
CDFs for a comparison over a single distribution, linear combinations
of normals…). See Continuous Distributions for the full
surface.
When is exact evaluation tractable?
Computing the exact probability is  -hard in general
[Dalvi and Suciu, 2007], but several structural restrictions make
it tractable, and ProvSQL recognises each and evaluates it with a
dedicated method. Each row below is a
sufficient condition for tractability, classified by the shape of the
data, of its probabilistic annotation (TID = tuple-independent,
BID = block-independent-disjoint, correlated = arbitrary, e.g.,
view-derived), and of the query. ProvSQL applies whichever fits.
The query conditions are stated over classes of the relational calculus –
conjunctive queries (CQ) and unions of them
(UCQ) – which ProvSQL recognises from the structure of ordinary SQL queries.
All complexities are data complexity: the query is fixed, so its size is
not counted.  is the input size (number of tuples),
 the
treewidth relevant to each row (provenance, data, or joint treewidth), and
 the number of essential query variables.
Data
Annotation
Query
Complexity
Source
ProvSQL mechanism
any
TID / BID
hierarchical, self-join-free CQ
safe-query rewrite, then
independentany
TID
inversion-free UCQ (self-joins allowed)
inversion-free certification, then
inversion-freeany
TID
safe UCQ needing Möbius inversion (self-join-free)
Möbius compiler, then the signed Möbius sweep over
independentislandsany query whose provenance over this data and annotations has treewidth ≤ k
in-process tree-decomposition method
treewidth ≤ k (treelike)
TID / BID
recursive reachability
reachability compiler, then
independentjoint treewidth ≤ k of the data and its annotation
any UCQ
[Amarilli, 2016] (§4.2)
joint-width compiler, then
independent


For the exact guarantee, the cost-based chooser
always tries independent and inversion-free when their certificate
applies (they are cheap and read-once-friendly), and tries
tree-decomposition when it estimates the provenance treewidth low enough to
stand a chance.
Outside these sufficient conditions, when the provenance is genuinely
-hard with no structure to exploit, no exact polynomial guarantee
remains, and ProvSQL falls back to knowledge compilation (compilation /
wmc) for an exact answer or to an FPRAS (monte-carlo / karp-luby)
for an approximate one (see Forcing a specific method).
Specialised routes for hard queries
For two query families ProvSQL compiles a certified circuit
along a tree decomposition of the data itself, turning a
-hard problem into one linear in the data. Both are exact and
need no external tool.
Network reliability on bounded-treewidth graphs
The first is two-terminal network reliability: the probability that a
vertex is reachable from a source in a probabilistic graph, following the
provenance refinement of Courcelle’s theorem
[Amarilli et al., 2015]. This problem is -hard in general,
but becomes solvable in time linear in the number of edges when the
graph has bounded treewidth – a property of many real networks
(series-parallel and outerplanar networks, transit and utility networks,
workflow graphs…).
The interface is an ordinary recursive reachability query, under
provsql.provenance = 'absorptive' or 'boolean' (see
provsql.provenance (default: 'semiring')), over a provenance-tracked edge relation
link whose tuples carry probabilities:
SET provsql.provenance = 'absorptive';

WITH RECURSIVE reach(node) AS (
    SELECT 1                                  -- the source vertex
  UNION
    SELECT e.dst FROM link e JOIN reach r ON e.src = r.node
)
SELECT node, probability_evaluate(provenance())
FROM reach WHERE node = 42;
Cyclic graphs are handled, and vertex columns of any type work (values are compared as text). The following variations are recognised too:
undirected connectivity:
SELECT CASE WHEN e.src = r.node THEN e.dst ELSE e.src END FROM link e JOIN reach r ON r.node IN (e.src, e.dst);a deterministic edge filter, a
WHEREclause over the edge relation’s columns alone (WHERE e.capacity >= 10);a source set in the base arm,
SELECT v FROM sources: certain sources ifsourcesis untracked, probabilistic ones if it is tracked (but not prepared withrepair_key);edge relations prepared with
repair_key(mutually exclusive alternative edges);a derived edge relation (a subquery or view over several tracked tables), provided no two derived edges share a base tuple;
bounded hops: a counter column seeded by an integer constant, incremented in the recursive arm and bounded by a mandatory
WHEREcondition (<or<=). Row(v, h)holds when some walk (not necessarily a simple path) of exactlyhedges reachesv, andSELECT node FROM reach GROUP BY nodegives the vertices within the bound:WITH RECURSIVE reach(node, hops) AS ( SELECT 1, 0 UNION SELECT e.dst, r.hops + 1 FROM link e JOIN reach r ON e.src = r.node WHERE r.hops < 4 ) SELECT node, hops, probability_evaluate(provenance()) FROM reach;
reachability per group: joining the reached vertices with an untracked relation and grouping by one of its columns (
... FROM reach r JOIN
regions t ON r.node = t.node GROUP BY t.region
, or theSELECT DISTINCTequivalent), optionally filtered on that relation’s own columns, gives the probability that some vertex of each group is reachable;k-terminal reliability: a self-join of the CTE fixing one vertex per reference (
FROM reach r1, reach r2, reach r3 WHERE r1.node = 5 AND r2.node = 6 AND r3.node = 9) gives the probability that all are reachable.
Any other shape, or data whose treewidth exceeds the cap of the
tree-decomposition method, falls back to the generic recursive
evaluation, with the same result. Set provsql.verbose_level to at
least 10 for a notice when this happens, or 20 to confirm the compiled
route.
The circuits produced are certified deterministic and decomposable
(d-Ds), so probability_evaluate is linear on them, and
shapley, banzhaf and ddnnf_stats need no
external compiler. Shapley values of the edge tuples measure the
criticality of each edge:
SELECT src, dst, shapley(reach_token, provenance()) AS criticality
FROM link;
The same circuits evaluate exactly in every absorptive semiring [Deutch et al., 2014]. The nonnegative min-plus semiring gives min-cost reachability (shortest distances, constrained by the hop budget in the bounded-hop variant, per-group minima, and the directed Steiner cost in the k-terminal form, shared edges paid once):
SELECT node, sr_tropical(provenance(), 'cost_mapping',
nonnegative => true) AS min_cost
FROM reach;
Likewise sr_viterbi gives the most reliable path,
sr_maxmin the widest path, sr_lukasiewicz the best
fuzzy path, and sr_temporal the instants at which a vertex is
reachable (see Temporal Features). The result carries the
'absorptive' assumption (get_gate_type reports its root as
assumed): semirings that are not absorptive, such as counting and
why-provenance, raise an error on it instead of returning a wrong value,
while sr_formula, which does not evaluate the circuit but
displays it, shows the compiled circuit as it is.
Bounded joint width: hard UCQs over correlated data
Safe-query rewriting and the inversion-free class only apply to
tractable queries, and not over correlated inputs. ProvSQL also
evaluates -hard UCQs, such as 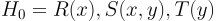 , exactly, over inputs that may be correlated, when their
joint width is small: the treewidth of the data together with its
correlation structure [Amarilli, 2016] (§4.2). The cost is
then linear in the data.
The route takes the same opt-in as safe-query rewriting, the 'boolean' provenance class, and then
applies automatically to a UCQ the safe-query rewriter declined, whose
existence is formed by a SELECT DISTINCT or a GROUP BY:
SET provsql.provenance = 'boolean';
-- H0 = R(x), S(x, y), T(y): #P-hard, evaluated here per group
SELECT t.id, probability_evaluate(provenance())
FROM r, s, t
WHERE r.x = s.x AND s.y = t.y
GROUP BY t.id;
It is the only exact route over correlated inputs
(repair_key blocks, view-derived provenance) in the
tractability table. When the joint width exceeds
the supported cap or the query shape is not recognised, the query is
evaluated on its ordinary circuit by the general chooser; set
provsql.verbose_level to confirm which route ran, or
provsql.joint_width off to disable the route. Case Study 7, Step 9, walks a worked example.
Forcing a specific method
Normally you request a guarantee and the cost-based chooser
(Choosing a guarantee, not a method) selects among the methods below. You can
also name one explicitly as the second argument of
probability_evaluate – to force an algorithm, to understand a
plan, or when you know your circuits better than the cost model. This
table summarises where each shines:
Method |
Guarantee |
Best when (query / provenance circuit) |
|---|---|---|
|
exact |
Read-once provenance (self-join-free / hierarchical CQs, each input tuple used at most once). Linear time. |
|
exact |
The |
|
exact |
Safe (inversion-free) UCQs the planner certifies – linear-time via a structured d-DNNF even with self-joins. |
|
exact |
Safe UCQs that are tractable only because the |
|
exact |
Very few input tuples (a couple of dozen at most): brute force over all
|
|
exact |
A comparison of aggregate results (a |
|
exact |
Few clauses: a small monotone-DNF provenance (inclusion-exclusion). |
|
exact |
Low-treewidth provenance – path-, cycle- or band-shaped join graphs; no external tool needed. |
|
exact / certified bounds |
High-treewidth circuits where |
|
exact |
Hard provenance with hidden structure a knowledge compiler can exploit; last-resort, needs an external tool (see Knowledge Compilation). |
|
depends on tool |
Hard provenance better suited to a weighted model counter than to a d-DNNF
compiler; an alternative external-tool route to |
|
additive |
Any circuit; cheap when the probability is not tiny. |
|
relative |
Rare events (small |
|
relative |
A universal relative estimator for any circuit – including random-variable and HAVING-aggregate provenance. |
Each method in detail:
'independent'Exact computation by a single linear pass that treats each gate as independent. It is correct on read-once provenance (each input tuple used at most once) and on the certified d-D circuits that the safe-query, reachability and joint-width compilers produce. It errors on a circuit that is neither:
SELECT probability_evaluate(provenance(), 'independent') FROM suspects;
When the circuit came from one of those three compilers, the default strategy reports it under that compiler’s own name instead (see
'sq-rewrite'/'bounded-jw'/'reachability'below); naming'independent'explicitly still works on such a circuit.
'sq-rewrite','bounded-jw','reachability'The three planner-time routes: the safe-query (read-once) rewriter, the joint-width UCQ compiler and the bounded-treewidth reachability compiler. Each replaces a query’s ordinary provenance with a circuit of its own, evaluated by the same linear pass as
'independent'. The method names record which route produced the circuit, soprovsql.last_eval_methoddistinguishes them instead of reportingindependentfor all four cases:SET provsql.last_eval_method = ''; SELECT probability_evaluate(provenance()) FROM reachable; SHOW provsql.last_eval_method; -- reachability
Naming one on a token the route did not produce is an error. The default strategy already picks the right one, so naming them explicitly is mainly useful for testing:
SELECT probability_evaluate(provenance(), 'reachability') FROM reachable;
'possible-worlds'Exact computation by exhaustive enumeration of all possible worlds. Exponential in the number of provenance tokens; practical only for small circuits:
SELECT probability_evaluate(provenance(), 'possible-worlds') FROM suspects;
'possible-worlds-aggregates'The same enumeration, computing the aggregates’ values in each world, for comparisons of aggregate results (
HAVING, the rank of aLIMIT). The chooser takes it when a comparison aggregates more rows than the circuit has input tuples, and these are at most 20, and for an aggregate over aggregate results (anavgof acount, see Aggregates of aggregate results):SELECT probability_evaluate(provenance(), 'possible-worlds-aggregates') FROM top_users;
'sieve'Exact computation by inclusion-exclusion over the clauses of a monotone-DNF provenance, in time
O(S × 2^m)formclauses. The chooser prefers it over'possible-worlds'when there are fewer clauses than input tuples, and over the compilers whenmis small. It applies only to a DNF-shaped circuit and errors when the clause count exceeds 24:SELECT probability_evaluate(provenance(), 'sieve') FROM suspects;
'monte-carlo'Approximate computation by random sampling. The third argument is either a fixed sample count (a bare integer or
samples=N) or an additive(ε, δ)targetepsilon=E[,delta=D][,max_samples=M](defaulteps=0.1, delta=0.05when omitted):SELECT probability_evaluate(provenance(), 'monte-carlo', '10000') FROM suspects; SELECT probability_evaluate(provenance(), 'monte-carlo', 'eps=0.01') FROM suspects;
The
(ε, δ)form guarantees that the estimate is withinεof the true probabilityp(in absolute terms) with probability at least1 − δ, drawingN = ⌈ln(2/δ)/(2ε²)⌉samples (Hoeffding’s inequality); the count is independent ofp. Because the error is absolute, anεof, say,0.1is uninformative on a rare-event output withp ≪ ε; for a relative-error guarantee in that regime use'karp-luby'. Pinprovsql.monte_carlo_seedfor a reproducible estimate.'karp-luby'Approximate computation by the Karp-Luby fully-polynomial randomised approximation scheme (FPRAS) for
#DNF[Karp et al., 1989]. It delivers a relative(ε, δ)guarantee – the estimate is within a factor1 ± εof the true probability with probability at least1 − δ– at a sample count independent of that probability. This is the guarantee that stays meaningful on rare-event outputs, where naive Monte Carlo’s absoluteε(see'monte-carlo'above) says nothing. It applies to DNF-shaped circuits: a monotone disjunction (top-levelOR) of conjunctions (AND) of input leaves – the provenance shape of a union of conjunctive queries over a tuple-independent database. Leaves may be shared across clauses. The method errors (it does not silently fall back) on any other shape: negation (EXCEPT/monus), comparison (HAVING), aggregation, random-variable, or multivalued (BID) gates.The third argument selects a fixed sample count or an
(ε, δ)accuracy target (defaultepsilon=0.1, delta=0.05when omitted):samples=N(or a bare integerN) – a fixed number of sampling rounds; deterministic runtime.epsilon=E(aliaseps=E) – relative-error target: the method samples only until the estimate is provably within the target, so on outputs whose clauses barely overlap it stops far short of the worst-case⌈4(e−2)·m·ln(2/δ)/ε²⌉rounds over themclauses.delta=D– failure-probability target (only withepsilon).max_samples=N– caps the number of rounds (only with the adaptive path), bounding the runtime for very smallεor largem; if the cap is hit before the target, the reported guarantee is downgraded to the accuracy actually achieved.
-- fixed budget SELECT probability_evaluate(provenance(), 'karp-luby', '100000') FROM suspects; -- (ε, δ) guarantee SELECT probability_evaluate(provenance(), 'karp-luby', 'eps=0.05,delta=0.01') FROM suspects;
samplesis mutually exclusive withepsilon/delta. Pinprovsql.monte_carlo_seedfor a reproducible estimate.'stopping-rule'A universal relative
(ε, δ)estimator that runs on the generic circuit, so unlike'karp-luby'it applies to any provenance – plain Boolean, random-variable, or HAVING-aggregate alike. It stops sampling as soon as the estimate is provably within the relative target, inO(S / (p ε²) · ln(1/δ))for an output of probabilityp. The third argument is the(ε, δ)target (with an optionalmax_samplescap; if the cap is reached first the guarantee degrades from relative to the additive accuracy actually achieved). Pinprovsql.monte_carlo_seedfor a reproducible estimate:SELECT probability_evaluate(provenance(), 'stopping-rule', 'eps=0.05,delta=0.01') FROM suspects;
'tree-decomposition'Exact computation via a tree decomposition of the Boolean circuit [Amarilli et al., 2020]. Built-in; no external tool required. Fails if the treewidth exceeds the maximum supported value:
SELECT probability_evaluate(provenance(), 'tree-decomposition') FROM suspects;
'd-tree'Anytime certified-interval computation [Olteanu et al., 2010]: starting from cheap bounds, it refines a certified interval until it is narrow enough, or exact (width 0). It fills two corners the other exact methods do not: it returns an exact value where the provenance treewidth exceeds
'tree-decomposition'’s cap, and, being deterministic (its cost does not depend onδ), it honours aδ = 0(no-failure) approximate request, returning a certified interval rather than a point estimate. It works on any Boolean circuit. Called by name with no third argument it refines to the exact value; given an accuracy target it stops at a certified interval of that width:SELECT probability_evaluate(provenance(), 'd-tree') FROM suspects;
'inversion-free'Exact, linear-time computation for the inversion-free
UCQ(OBDD)class [Jha and Suciu, 2011] – hierarchical, tuple-independent queries (self-joins allowed) whose provenance admits a polynomial-size OBDD, where'tree-decomposition'would blow up. It requires the planner’s inversion-free certificate on the provenance root and errors without it. The default strategy already takes this path automatically when the certificate is present, so naming the method is mainly useful for testing; see Inversion-free certification for what the certifier accepts:SELECT probability_evaluate(provenance(), 'inversion-free') FROM suspects;
'mobius'Exact computation for the safe UCQs that need Möbius inversion – those tractable only because the
-hard
terms of their inclusion-exclusion expansion cancel (the  /
 class). It applies to the
gate_mobius-rooted token ProvSQL produces for such a query, in linear time, and errors on any other token. Naming another method on the same token ('possible-worlds','monte-carlo'…), or asking forshapley/banzhaf, evaluates the query’s literal provenance instead and returns the same exact answer, more slowly. The default strategy already takes the Möbius route for such a token, so naming it explicitly is mainly useful for testing:SELECT probability_evaluate(provenance(), 'mobius') FROM safe_ucq;
'compilation'Exact computation by first compiling the circuit to a d-DNNF using an external tool, then evaluating the d-DNNF. The third argument names the tool:
'd4'(default),'d4v2','c2d','dsharp','minic2d', or one of the Panini target languages from KCBox [Lai et al., 2025],'panini-obdd','panini-obdd-and'[Lai et al., 2017],'panini-decdnnf':SELECT probability_evaluate(provenance(), 'compilation', 'd4') FROM suspects;
The tool must be installed and accessible in the PostgreSQL server’s PATH, or in a directory listed in the
provsql.tool_search_pathGUC (see Configuration Reference);tool_availablereports the backend’s view of a given tool. The CNF handed to the compiler and the resulting d-DNNF can both be inspected; see Knowledge Compilation.'wmc'Weighted model counting (umbrella over several counters); the guarantee depends on the chosen tool –
'ganak'/'sharpsat-td'/'dpmc'are exact,'weightmc'is an approximate(ε, δ)counter. The third argument selects the counter and its options astool=<name>[,epsilon=E][,delta=D](atool[;tool_args]form is also accepted):'ganak'[Sharma et al., 2019],'sharpsat-td'[Korhonen and Järvisalo, 2021],'dpmc'[Dudek et al., 2020], or'weightmc'. Same PATH /provsql.tool_search_pathconsiderations as'compilation':SELECT probability_evaluate(provenance(), 'wmc', 'ganak') FROM suspects;
- Default strategy (no second argument)
With no method named,
probability_evaluate(provenance())requests the exact guarantee, and the cost-based chooser (see above) runs the cheapest exact method applicable to the circuit: typicallyindependentorinversion-freefor safe queries,tree-decompositionfor low-treewidth provenance, falling back tocompilationwith the compiler named byprovsql.fallback_compiler(default'd4', see Configuration Reference) when no in-process method fits. Optimistic picks run under a budget and escalate automatically, so a pathological circuit never hangs on the wrong method.The empty default is identical to an explicit
'exact'request on an ordinary Boolean circuit, with one exception. On a circuit carrying continuous random variables (see Continuous Distributions), some comparison events have no closed form and depend on correlations that cannot be marginalised analytically (for instance conditioning on a mixture’s own Bernoulli selector, or a comparison over a combination of mixtures). For those the empty default falls back to the Monte Carlo sampler (an approximate(ε, δ)estimate at theprovsql.rv_mc_samplesbudget), whereas an explicit'exact'request raises an error instead of returning an estimate; name'monte-carlo'explicitly to opt in.provsql.rv_mc_samples = 0disables the fallback, and the default then raises as well.
To time every method on one circuit and compare results side by side, use ProvSQL Studio’s benchmark panel; see ProvSQL Studio.
Performance optimisations under the hood
Six optimisations exploit Boolean-specific structure to make probability evaluation faster, sometimes by orders of magnitude; none changes the result.
Safe-query rewriting (provenance class 'boolean')
When the provenance class is 'boolean' (provsql.provenance, off by
default), the planner recognises the safe hierarchical
conjunctive-query subclass of Dalvi-Suciu [Dalvi and Suciu, 2012]
and rewrites such queries so that their provenance circuit is
read-once, evaluated in linear time by the 'independent' method
instead of 'tree-decomposition' or external compilation.
The rewriter recognises self-join-free hierarchical conjunctive queries over TID or BID base tables, plus a number of extensions that recover safety for query shapes the raw hierarchical criterion would reject (FD-aware reductions driven by primary keys / NOT-NULL UNIQUE constraints, constant selections, transparent deterministic relations, certain self-joins, UCQs with disjoint branches…); see Safe-Query Rewriter in the developer documentation for the full set. Queries outside the recognised class are passed through unchanged: the setting enables an opt-in shortcut, never a different result.
SET provsql.provenance = 'boolean';
SELECT person, ROUND(probability_evaluate(provenance())::numeric, 4)
FROM suspects, witnesses
WHERE suspects.case_id = witnesses.case_id;
Trade-off. Semiring evaluators incompatible with Boolean rewriting
refuse to run on the result (see Semiring Evaluation for the compatibility
list). In practice: use the 'boolean' class for probability-heavy
workloads on hierarchical CQs, and switch it off (or re-evaluate in a
fresh session) before running sr_counting, sr_how,
sr_why on the same circuit.
Inversion-free certification
The inversion-free UCQ(OBDD) class of Jha & Suciu
[Jha and Suciu, 2011] – hierarchical, tuple-independent queries
whose provenance admits a polynomial-size OBDD – is a second linear-time
route for safe queries, a sibling of the safe-query rewrite. ProvSQL certifies the query and the default
chooser takes the route automatically, right after 'independent', so
no method need be named. It stays linear in the provenance where
'tree-decomposition' would blow up because the provenance is not
low-treewidth.
It differs from the safe-query rewrite on three counts:
Self-joins. The inversion-free class natively admits queries that join a relation with itself; the safe-query rewrite targets self-join-free CQs and recovers only limited self-join cases.
Provenance scheme. The inversion-free route evaluates the literal provenance unchanged, so it does not require the
'boolean'provenance class (it applies under the default semiring scheme too), and is governed by its ownprovsql.inversion_freeGUC (on by default). The safe-query rewrite restructures the query and fires only underprovsql.provenance = 'boolean'.Edge cases. In exchange it certifies fewer shapes: the safe-query rewrite recovers safety from functional dependencies and BID blocks (see Safe-query rewriting (provenance class 'boolean')), which the inversion-free certifier does not: its atoms must be strictly tuple-independent. (A plain constant selection is fine either way: the certifier treats it as a transparent atom-local filter.)
The certifier does let a non-tracked relation act as a transparent
filter, and flattens SPJ subqueries and views before checking the
class: a join inside a view, a view referenced several times (a
structured self-join), and views-over-views all reduce to their base
atoms first. An aggregating or UNION view, a correlated subquery,
or a query still non-hierarchical after flattening is not certified and
falls back to another method. See The Inversion-Free UCQ(OBDD) Path in the
developer documentation for the full pipeline.
Möbius inversion for safe UCQs
Some unions of conjunctive queries are safe (PTIME data complexity)
while being neither hierarchical nor inversion-free: they are
tractable only because the -hard terms of their
inclusion-exclusion expansion carry a zero Möbius coefficient and
cancel. The canonical witness is Dalvi & Suciu’s /
[Dalvi and Suciu, 2012]; the lattice
computation follows Dalvi, Schnaitter & Suciu (PODS 2010). Under the
'boolean' provenance class, when the safe-query rewriter and the
inversion-free certifier both decline a UCQ-existence shape (a
SELECT DISTINCT / GROUP BY over a UNION), ProvSQL
recognises this class and replaces the provenance with a signed Möbius
combination of read-once parts, which the default probability
evaluation handles in one linear pass; no method needs to be named.
Case Study 7 runs the complete
example.
This is a shortcut, not a different result, and unlike the safe-query
rewrite it keeps the query’s literal provenance, so shapley,
banzhaf, PROV export, and any named probability method
(possible-worlds…) answer exactly as on the ordinary provenance,
necessarily more slowly, since the literal provenance is the
-hard circuit the cancellation avoids. Only the default / mobius probability
takes the fast route.
The route runs in  ( the essential-variable
count), so the linear hierarchical and inversion-free routes are
tried first. Where it applies, it takes precedence over the
joint-width compiler, whose success on
these queries is not guaranteed. Inputs must be tuple-independent,
with one probabilistic tuple per element tuple and no two query slots
sharing a base tuple; anything else falls back to joint width, then
the general chooser.
provsql.mobius (on by default), the
provsql.mobius_max_gates data-cost cap and the
provsql.mobius_max_cnf query-cost cap control the route.
Self-joins are handled, except a self-join carrying an inversion
(S(x,y),S(y,x)), which is outside every tractable class.
HAVING closed-form shortcuts
For the common GROUP BY g HAVING <agg> op c thresholds (op one of
>=, >, <=, <, =, <>) ProvSQL computes the group’s
probability in closed form, replacing the exponential DNF the general
HAVING path would build. Each applies automatically, with no setting to
change, when each row’s provenance is a single input token and the
group’s aggregate is not shared with another comparison.
COUNT. COUNT(*) op c is computed as a Poisson-binomial
distribution over the rows’ presence, in
O(N × min(C, N−C)) per group (N the per-group row count).
HAVING-COUNT queries that would otherwise hit 'tree-decomposition' or
'compilation' resolve in milliseconds. A multi-comparator HAVING
(COUNT(*) >= a AND COUNT(*) <= b) falls through to the general path.
MIN / MAX. MIN(a) op c and MAX(a) op c are computed as a
product of the rows’ presence probabilities, in O(N) per group. For
example,
MAX(a) >= c holds iff at least one row with a >= c is present,
with probability 1 − ∏ (1 − p_i) over those rows; MIN(a) >= c
holds iff no row with a < c is present and the group is non-empty.
All twelve (MIN|MAX, op) cases have analogous closed forms.
SUM. SUM(a) op c is computed from the distribution of the
group’s sum (the empty group excluded), in O(N × R) per group with
R the range of reachable sums. Because R grows with the
magnitude of the values, the shortcut is pseudo-polynomial and steps
aside for the general path when the range is too wide; for the usual
small-integer values it replaces the exponential enumeration with a fast
computation.
Folding independent parts
When the lineage is a conjunction or a disjunction of parts that share
no input tuple, ProvSQL evaluates each part on its own, with the method
that suits it, and combines the results. A query whose answer gathers
many unrelated groups (the lines of each order, the papers of each
reviewer) is then as easy as its hardest group. This happens under the
default method; provsql.idp_fold turns it off,
or extends it to a method called by name. Such an evaluation is listed
as fold in provsql.last_eval_method,
followed by the methods used on the parts.
Reusing compiled d-DNNFs
Within a session, ProvSQL keeps the d-DNNFs that
'tree-decomposition' and 'compilation' build, and reuses one
whenever a lineage of the same shape comes back, over other tuples or
with other probabilities: the answers of one query often share a shape.
This too happens under the default method;
provsql.prob_cache turns it off, or extends
it to a method called by name. An answer served this way is listed as
cache:<method> in
provsql.last_eval_method.