Case Study: Wildlife Photo Archive
This case study, loosely inspired by a ProvSQL demonstration at EDBT 2025
[Yunus et al., 2025], applies ProvSQL to a database of wildlife
photographs annotated by a species-detection model. It demonstrates the
VALUES clause, repair_key and the mulinput gate, ranking
by probability versus thresholding, EXCEPT, common table expressions,
expected aggregates, and the choose aggregate.
The Scenario
A naturalist organisation maintains a database of wildlife photographs taken at four field stations in the Scottish Highlands. Each photo has been processed by a species-detection model that draws one or more bounding boxes around things it thinks are animals, and for each box reports a list of candidate species with a confidence score. A box can therefore appear with several species candidates (e.g., a partly-occluded shape might score 0.40 as red deer and 0.30 as roe deer); a photo can contain several boxes of the same species (e.g., three deer in a meadow shot).
Your tasks:
find photos that contain specific combinations of species,
rank results by the probability that the combination is truly present,
compare probabilistic ranking against naive confidence thresholding,
exclude photos that contain unwanted species,
compute expected species counts per photo,
read the label of each bounding box as a distribution.
Setup
Tip
Prefer not to install? Use the Playground. You can skip the manual setup below: open this case study as a runnable notebook in the ProvSQL Playground (every query is a cell, and the opening cells set up the database for you), or open the bare cs5 database and run the queries as you read. See the Playground note.
This case study assumes a working ProvSQL installation (see
Getting ProvSQL). Download setup.sql
and load it into a fresh PostgreSQL database:
psql -d mydb -f setup.sql
The setup script calls setup_search_path, which adds
provsql to the database’s search_path: every new session calls
ProvSQL’s functions without the provsql. prefix.
This creates three tables:
photo– 30 wildlife photographs, each tagged with a station name (Loch Torridon, Glen Affric, Rannoch Moor, or Cairngorms) and a datespecies– 13 species across mammals, birds, and reptilesdetection– about 60 model-produced (bounding-box, species) candidate rows, each linking a photo and a bounding-box index to a candidate species with a confidence score; multiple rows for the same (photo_id,bbox_id) pair represent the classifier’s alternative species hypotheses for that single bounding box
Step 1: Explore the Database
Inspect the tables. detection is not keyed on
(photo_id, bbox_id): a single bounding box can appear in
several rows, one per candidate species the classifier considered.
SELECT * FROM photo  ORDER BY id LIMIT 5;
SELECT * FROM species ORDER BY id;
SELECT photo_id, bbox_id, species_id, confidence
FROM detection
WHERE photo_id IN (5, 9, 14, 22)
ORDER BY photo_id, bbox_id, confidence DESC;
Step 2: Enable Provenance and Create a Name Mapping
Enable provenance tracking on detection. Each row receives a UUID
circuit token that propagates through any downstream query.
SELECT add_provenance('detection');
To get readable formulas, we want to associate each detection’s
provenance token with its species name. A provenance mapping in
ProvSQL is a regular table with two columns named value and
provenance (plus, for performance, an index on provenance).
create_provenance_mapping builds such a table from one column
of a provenance-enabled relation; here we construct it by hand:
DROP TABLE IF EXISTS species_mapping;
CREATE TABLE species_mapping AS
  SELECT s.name AS value, d.provsql AS provenance
  FROM detection d JOIN species s ON s.id = d.species_id;

SELECT remove_provenance('species_mapping');
CREATE INDEX ON species_mapping(provenance);
The CREATE TABLE AS query inherits a provsql column from
detection; remove_provenance strips it so only the
(value, provenance) pair remains. A mapping can be populated from
any expression – combine columns, filter rows, derive computed values –
and any semiring-evaluation function (sr_formula, sr_why…)
accepts the result. Such a table is a snapshot, though: rows inserted
into detection later are not added to it, and a row whose input token
replace_input replaces keeps its value under the old token. A
mapping built by create_provenance_mapping follows a replaced
token, and, created with maintained => true, new rows too.
Step 3: Inline Lookup with VALUES
A VALUES clause defines an inline relation directly inside a query.
ProvSQL treats it like any other source: its rows have no provenance of
their own, and a join with them inherits provenance from the
provenance-enabled rows.
Here we use VALUES to define a small ad-hoc watchlist: a couple of
species we want to look up by hand together with a human-readable
label, instead of pulling them from the species table. Suppose we
are interested in Red Deer (species_id 1, the dominant grazer
whose density we want to track) and Red Fox (species_id 3, a
generalist predator), and we want to tag the rows accordingly:
SELECT v.label, p.id, p.station, p.date,
       sr_formula(provenance(), 'species_mapping') AS formula
FROM (VALUES (1, 'mammal of interest'),
             (3, 'predator of interest')) AS v(species_id, label),
     detection d, photo p
WHERE d.species_id = v.species_id AND d.photo_id = p.id
ORDER BY p.id, v.label;
Each output row carries the provenance of the underlying detection
row alone: the formula is a single species token, even though the row
also references photo and VALUES. Tables without provenance –
including the VALUES rows – contribute no tokens.
Step 4: Conjunctive Query (Naive)
Find photos that contain both Red Deer (species_id 1) and Red Fox
(species_id 3) using a self-join on detection:
SELECT p.id, p.station, p.date,
       sr_formula(provenance(), 'species_mapping') AS formula
FROM detection d1
JOIN detection d2 ON d1.photo_id = d2.photo_id
JOIN photo p ON p.id = d1.photo_id
WHERE d1.species_id = 1 AND d2.species_id = 3
GROUP BY p.id, p.station, p.date
ORDER BY p.id;
Look at photo 5: the classifier produced three Red Deer candidate rows
(in bounding boxes 1, 2 and 3) and two Red Fox candidate rows (in boxes
4 and 5). Its formula is the ⊕-sum of all six (deer, fox) pair products
– every candidate row is an independent input. For these five boxes,
that is right; but in box 1, the classifier also proposed a Roe Deer.
A bounding box shows at most one real animal, so its Red Deer and Roe
Deer rows cannot both be right: candidate rows that share a
(photo_id, bbox_id) pair should be mutually exclusive rather than
independent. Nothing in the schema says so, and the provenance treats
them as independent.
Step 5: Mutually Exclusive Candidates with repair_key
repair_key rewrites the provenance so that rows sharing a key
become alternatives under a single mulinput (multivalued input) gate,
i.e., at most one of them is true (none, with what probability the
candidates leave). Applied with the key
(photo_id, bbox_id), every bounding box becomes one mulinput
variable whose values are the candidate species the classifier
considered for that box.
The key is given as a comma-separated list of columns.
repair_key reinstalls the provsql column itself, so also drop
the old mapping (whose tokens are about to become stale):
DROP TABLE species_mapping;
SELECT remove_provenance('detection');

SELECT repair_key('detection', 'photo_id,bbox_id');

DROP TABLE IF EXISTS species_mapping;
CREATE TABLE species_mapping AS
  SELECT s.name AS value, d.provsql AS provenance
  FROM detection d JOIN species s ON s.id = d.species_id;
SELECT remove_provenance('species_mapping');
CREATE INDEX ON species_mapping(provenance);
Re-run the conjunctive query from Step 4, with sr_formula and
with sr_boolexpr, which renders the underlying Boolean formula;
the mapping labels each candidate by its species in both:
SELECT p.id,
       sr_formula(provenance(), 'species_mapping') AS formula,
       sr_boolexpr(provenance(), 'species_mapping') AS bexpr
FROM detection d1
JOIN detection d2 ON d1.photo_id = d2.photo_id
JOIN photo p ON p.id = d1.photo_id
WHERE d1.species_id = 1 AND d2.species_id = 3 AND p.id IN (2, 5)
GROUP BY p.id
ORDER BY p.id;
In the Boolean expression, each candidate is now the value of a
multivalued variable: {i=v}[p] reads “variable i takes value
v, with probability p”, and the candidates of one bounding box are
values of the same variable, at most one of which holds. The formula
shows the candidates by their labels only: mutual exclusion concerns the
probabilities of the candidates, which a semiring does not see. In this
query every variable happens to have a single value, so the mutually
exclusive structure is not visible yet. We will see a genuine
multi-valued variable in the next step, where the deer/roe-deer
candidates of one bounding box compose under the mutex constraint.
view_circuit draws the same structure: each candidate a leaf
with its label, wired to the variable it is a value of (⋮).
Step 6: Assign Probabilities and Verify Mutual Exclusion
Each candidate row’s confidence becomes the probability that that classifier candidate is the true species for its bounding box:
SELECT set_prob(provenance(), confidence) FROM detection;
To see that repair_key made a numerical difference, ask: what is
the probability that bounding box 1 of photo 5 corresponds to a
deer-like animal (species_id 1 = Red Deer or 2 = Roe Deer)? In the
data, that bounding box has both candidate species recorded with
confidences 0.40 and 0.30:
SELECT photo_id, bbox_id,
    sr_boolexpr(provenance(), 'species_mapping') AS bexpr,
    ROUND(probability_evaluate(provenance(), 'tree-decomposition')::numeric, 4) AS p
FROM detection
WHERE photo_id = 5 AND bbox_id = 1 AND species_id IN (1, 2)
GROUP BY photo_id, bbox_id;
The Boolean expression is now
{0=Red Deer}[0.400000] ∨ {0=Roe Deer}[0.300000]: a single
multivalued variable (variable 0) with two mutually exclusive values,
Red Deer with probability 0.40 and Roe Deer with probability 0.30. Probability evaluation gives
0.7000, the sum of the two confidences, since combining mutually
exclusive events with ⊕ is just addition. Had we kept the original
add_provenance setup with each row as an independent input,
the same query would have given
1 - (1 - 0.40) × (1 - 0.30) = 0.58 instead. The 0.12 gap is the
practical effect of telling the engine “these candidates cannot both
be true at once”.
Step 7: Probabilistic Ranking vs. Threshold Filtering
Run the conjunctive query under two ranking strategies. First, by probability that both species are truly present:
SELECT p.id, p.station, p.date,
       ROUND(probability_evaluate(provenance())::numeric, 4) AS prob
FROM detection d1
JOIN detection d2 ON d1.photo_id = d2.photo_id
JOIN photo p ON p.id = d1.photo_id
WHERE d1.species_id = 1 AND d2.species_id = 3
GROUP BY p.id, p.station, p.date
ORDER BY prob DESC, p.id;
Second, by raw confidence threshold (every contributing detection must score at least 0.5):
SELECT DISTINCT p.id, p.station, p.date
FROM detection d1
JOIN detection d2 ON d1.photo_id = d2.photo_id
JOIN photo p ON p.id = d1.photo_id
WHERE d1.species_id = 1 AND d2.species_id = 3
  AND d1.confidence >= 0.5 AND d2.confidence >= 0.5
ORDER BY p.id;
Photo 5 is missed by thresholding (every individual candidate there
scores below 0.5) but ranks reasonably under
probability_evaluate, because the weak deer candidates in
several boxes plus the weak fox candidates combine into a non-trivial
probability that some deer and some fox are truly there.
Conversely, a photo whose top candidates only barely cross 0.5 passes
the threshold but ends up low in the probability ranking.
Step 8: Absence Constraint with EXCEPT
Find photos that contain a Red Deer but no Domestic Dog (species_id
13). ProvSQL represents EXCEPT with the ⊖ (monus) operator:
SELECT p.id, p.station, p.date,
       ROUND(probability_evaluate(provenance())::numeric, 4) AS prob
FROM (
    SELECT photo_id FROM detection WHERE species_id = 1
  EXCEPT
    SELECT photo_id FROM detection WHERE species_id = 13
) t
JOIN photo p ON p.id = t.photo_id
GROUP BY p.id, p.station, p.date
ORDER BY prob DESC, p.id;
Photos that contain a dog still appear in the output – EXCEPT is
not a hard filter. Photo 9, with a high-confidence dog detection,
ranks lower because the monus discounts strongly. Photo 14, where the
dog detection has very low confidence, ranks higher: it is probably
in the result, but not certainly. ProvSQL preserves both possibilities
in the circuit and lets probability_evaluate weigh them.
Step 9: Multi-Condition Query via a CTE
Combine Steps 7 and 8: photos with both Red Deer and Red Fox, with no Domestic Dog, ranked by probability. The query has three logical layers (co-occurrence, absence, ranking) and reads naturally as a CTE:
WITH deer_and_fox AS (
  SELECT d1.photo_id
  FROM detection d1
  JOIN detection d2 ON d1.photo_id = d2.photo_id
  WHERE d1.species_id = 1 AND d2.species_id = 3
  GROUP BY d1.photo_id
),
no_dogs AS (
  SELECT photo_id FROM deer_and_fox
  EXCEPT
  SELECT photo_id FROM detection WHERE species_id = 13
)
SELECT p.id, p.station, p.date,
       ROUND(probability_evaluate(provenance())::numeric, 4) AS prob
FROM no_dogs t
JOIN photo p ON p.id = t.photo_id
ORDER BY prob DESC, p.id;
Provenance propagates through CTEs transparently; the same answer can be written with nested subqueries.
Step 10: Expected Species Counts with expected
How many distinct species do we expect to really be in each photo?
COUNT(DISTINCT species_id) answers it, next to COUNT(*), which
counts detections:
SELECT p.id, p.station,
       ROUND(expected(COUNT(DISTINCT d.species_id))::numeric, 4) AS exp_species,
       ROUND(expected(COUNT(*))::numeric, 4) AS exp_detections
FROM detection d
JOIN photo p ON p.id = d.photo_id
GROUP BY p.id, p.station
ORDER BY exp_species DESC, p.id;
A group’s row is there only in the worlds where one of its detections is,
and the expectation is over those: expected(COUNT(*)) is
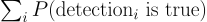 divided by the
probability that the photo keeps a detection at all.
expected(COUNT(DISTINCT d.species_id)) sums, over the species instead,
the probability that at least one detection of that species is true,
with the same division. The two differ as soon as a species is detected
in several bounding boxes: photo 1 has three Red Deer boxes, so about
2.19 expected detections but exactly one species, whichever boxes are
real. As in SQL, COUNT(DISTINCT …) ignores NULL: the
unidentified animal of photo 9 (more on it in Step 12) counts as a
detection, not as a species.
The same holds of SUM aggregates: the expected total confidence mass
per photo:
SELECT p.id, p.station,
       ROUND(expected(SUM(d.confidence))::numeric, 4) AS exp_total_conf
FROM detection d
JOIN photo p ON p.id = d.photo_id
GROUP BY p.id, p.station
ORDER BY exp_total_conf DESC, p.id;
These queries use ProvSQL’s expected operator, which computes
the expected value of a SQL aggregate over the probabilistic database
defined by the per-row probabilities set in Step 6. Photo 22, with six
bounding boxes and three species among them, ranks highest on every
metric.
Step 11: Materialising a Subset with INSERT … SELECT
Copying provenance-tracked rows into another provenance-tracked table
preserves their lineage: the inserted rows keep their source tokens rather
than getting fresh ones. Collect the high-confidence detections into a
confident_detections table – enable provenance on the target first,
then populate it with INSERT … SELECT:
CREATE TABLE confident_detections (
  photo_id   integer,
  bbox_id    integer,
  species_id integer,
  confidence double precision);
SELECT add_provenance('confident_detections');

INSERT INTO confident_detections (photo_id, bbox_id, species_id, confidence)
SELECT photo_id, bbox_id, species_id, confidence
FROM detection
WHERE confidence >= 0.9;
Each inserted row inherits the provenance token of the detection row it
came from, so a probability computed over confident_detections matches the
one over the original row – the lineage followed the data:
SELECT photo_id, species_id, confidence,
       ROUND(probability_evaluate(provenance())::numeric, 4) AS prob
FROM confident_detections
ORDER BY photo_id, species_id;
Note
The target table must be provenance-tracked before the insert. Inserting
provenance-tracked rows into an untracked table drops the lineage, with
a warning; use add_provenance on the target first (or
CREATE TABLE … AS SELECT, which carries provenance through directly).
Step 12: Unidentified Detections – Four Kinds of “Not”
Two detections in the archive have no species assignment: the
classifier saw an animal but could not identify it, and species_id
is NULL (photo 5 at Loch Torridon, confidence 0.60, and photo 9 at Glen
Affric, confidence 0.50). NULLs make the natural ways of asking
“species detected at Loch Torridon but not at Glen Affric” genuinely
different questions – in SQL itself, and therefore in the provenance
and probabilities ProvSQL computes. Station names live in the
untracked photo table; joining it in restricts to a station
without touching the provenance (an untracked join partner contributes
the neutral 1, as in Step 3).
First, EXCEPT. SQL set difference matches tuples syntactically:
two NULLs count as the same value, so Loch Torridon’s unidentified
sighting is discounted by Glen Affric’s:
SELECT species_id,
       ROUND(probability_evaluate(provenance())::numeric, 4) AS prob
FROM (
  SELECT species_id FROM detection d
    JOIN photo p ON d.photo_id = p.id
  WHERE p.station = 'Loch Torridon'
  EXCEPT
  SELECT species_id FROM detection d
    JOIN photo p ON d.photo_id = p.id
  WHERE p.station = 'Glen Affric'
) t
ORDER BY species_id NULLS LAST;
The NULL row comes out at probability 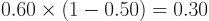 : an unidentified animal was seen at Loch Torridon and the Glen
Affric unidentified detection is a false positive.
Second, NOT IN. Under SQL’s three-valued logic, x NOT IN Q is
unknown – and therefore not an answer – as soon as Q contains a
NULL, whatever x is. A single unidentified sighting at Glen Affric
poisons the certification of every species:
SELECT species_id,
       ROUND(probability_evaluate(provenance())::numeric, 4) AS prob
FROM (
  SELECT DISTINCT species_id
  FROM (SELECT d.species_id FROM detection d
          JOIN photo p ON d.photo_id = p.id
        WHERE p.station = 'Loch Torridon'
          AND d.species_id NOT IN (SELECT d2.species_id FROM detection d2
                                     JOIN photo p2 ON d2.photo_id = p2.id
                                   WHERE p2.station = 'Glen Affric')) lt
) t
ORDER BY species_id NULLS LAST;
Every probability is exactly half its NOT EXISTS counterpart below:
each answer now carries the extra factor “the Glen Affric unidentified
detection is a false positive” (probability 0.50). The NULL row itself
drops to essentially 0 – a NULL can only pass NOT IN against an
empty set, i.e., in the worlds where no Glen Affric detection at all
is a true positive.
Third, NOT EXISTS with an explicit equality. d2.species_id =
d.species_id is never true when either side is NULL, so the
unidentified sightings are simply ignored: Glen Affric’s removes
nothing, and Loch Torridon’s own NULL row survives at its full
detection probability (0.60):
SELECT species_id,
       ROUND(probability_evaluate(provenance())::numeric, 4) AS prob
FROM (
  SELECT DISTINCT species_id
  FROM (SELECT d.species_id FROM detection d
          JOIN photo p ON d.photo_id = p.id
        WHERE p.station = 'Loch Torridon'
          AND NOT EXISTS (SELECT 1 FROM detection d2
                            JOIN photo p2 ON d2.photo_id = p2.id
                          WHERE p2.station = 'Glen Affric'
                            AND d2.species_id = d.species_id)) lt
) t
ORDER BY species_id NULLS LAST;
Fourth, an outer join. Keeping the Loch Torridon sightings that find
no Glen Affric partner (LEFT JOIN … IS NULL) is the same
question as NOT EXISTS: the join condition is an equality, which never
matches a NULL. The padded rows carry the provenance of the absence of a
match, and the probabilities are those of NOT EXISTS, row for row:
SELECT species_id,
       ROUND(probability_evaluate(provenance())::numeric, 4) AS prob
FROM (
  SELECT DISTINCT d.species_id
  FROM detection d
    JOIN photo p ON d.photo_id = p.id
    LEFT JOIN (SELECT d2.species_id FROM detection d2
                 JOIN photo p2 ON d2.photo_id = p2.id
               WHERE p2.station = 'Glen Affric') g
      ON g.species_id = d.species_id
  WHERE p.station = 'Loch Torridon' AND g.species_id IS NULL
) t
ORDER BY species_id NULLS LAST;
Four idioms, three different answers – matching what vanilla SQL returns on each query, with possible-worlds-correct probabilities on top. The general rules behind this behaviour (which comparisons treat NULLs as unknown, where SQL switches to syntactic matching, and what that means for provenance circuits) are spelled out in the NULL semantics chapter.
Step 13: Species Seen at Both Stations
The positive question – species detected at both Loch Torridon and
Glen Affric – has the same two readings. INTERSECT matches tuples
syntactically, NULL included:
SELECT species_id,
       ROUND(probability_evaluate(provenance())::numeric, 4) AS prob
FROM (
  SELECT species_id FROM detection d
    JOIN photo p ON d.photo_id = p.id
  WHERE p.station = 'Loch Torridon'
  INTERSECT
  SELECT species_id FROM detection d
    JOIN photo p ON d.photo_id = p.id
  WHERE p.station = 'Glen Affric'
) t
ORDER BY species_id NULLS LAST;
The unidentified row comes out at 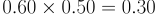 : both
unidentified sightings are true positives. A quantified comparison,
= ANY, compares values instead, and a NULL equals nothing:
SELECT species_id,
       ROUND(probability_evaluate(provenance())::numeric, 4) AS prob
FROM (
  SELECT DISTINCT d.species_id
  FROM detection d
    JOIN photo p ON d.photo_id = p.id
  WHERE p.station = 'Loch Torridon'
    AND d.species_id = ANY (SELECT d2.species_id FROM detection d2
                              JOIN photo p2 ON d2.photo_id = p2.id
                            WHERE p2.station = 'Glen Affric')
) t
ORDER BY species_id NULLS LAST;
The species rows are the same, and the unidentified row is gone. The
probabilities are consistent across queries: a species seen at Loch
Torridon is seen either at both stations or only there, so its
INTERSECT probability here and its EXCEPT probability in Step 12
add up to the probability that it is seen at Loch Torridon at all – for
the Red Deer, 0.9909 + 0.0091 = 1, and for the unidentified row,
0.30 + 0.30 = 0.60.
Step 14: The Label of Each Bounding Box
Since Step 5, the candidates of a bounding box are mutually exclusive: in each world, the label of the box is the candidate present, if any, with the probabilities of Step 6. Suppose instead that each candidate came from a detector of its own, one per species, so that both deer could be detected on box 1 of photo 5 at once. Copy the detections, each row an independent input:
CREATE TABLE detection_indep AS
  SELECT photo_id, bbox_id, species_id, confidence FROM detection;
SELECT remove_provenance('detection_indep');
SELECT add_provenance('detection_indep');
SELECT set_prob(provenance(), confidence) FROM detection_indep;
The copy inherits the provsql column of detection, with its
mutually exclusive tokens: remove_provenance drops it, and
add_provenance gives every row a token of its own.
To report one label per box, take the most confident candidate detected.
The choose aggregate picks one value of its group, in each
world the first in its ORDER BY among the rows present. Grouping by
that value turns it into a distribution over labels:
SELECT photo_id, bbox_id, label,
       ROUND(probability_evaluate(provenance())::numeric, 4) AS prob
FROM (
  SELECT d.photo_id, d.bbox_id,
         choose(s.name ORDER BY d.confidence DESC) AS label
  FROM detection_indep d JOIN species s ON s.id = d.species_id
  WHERE d.photo_id = 5
  GROUP BY d.photo_id, d.bbox_id
) t
GROUP BY photo_id, bbox_id, label
ORDER BY photo_id, bbox_id, label;
Red Deer, the more confident candidate of box 1, is its label whenever it
is detected, with probability 0.40. Roe Deer is the label only when
detected without Red Deer, with probability 0.60 × 0.30 = 0.18, and in the
remaining worlds no candidate is detected and the box has no label.
ORDER BY d.confidence would instead give Roe Deer 0.30 and Red Deer
0.70 × 0.40 = 0.28: when several candidates are present, the
ORDER BY of choose decides the label. On detection,
whose candidates are mutually exclusive, the same query returns the
confidences of Step 6 whatever the order, as at most one candidate is
ever present. Boxes 2 to 5 have a single candidate, and box 6, whose only
candidate is unidentified, has no species to join and no row.