Continuous Distributions
ProvSQL extends the probabilistic-database setting from discrete
Bernoulli inputs (see Probabilities) to continuous random
variables. Columns can carry distributions such as normal(μ, σ),
uniform(a, b), or exponential(λ); arithmetic and comparisons
apply to them; WHERE, JOIN and UNION work on
random-variable columns as ordinary SQL; and expected,
variance, moment, quantile, support, rv_sample and
rv_histogram query the resulting distributions, optionally
conditioned on filter predicates. Conditioning a random variable –
x | (x > k), which truncates and renormalises its distribution –
uses the same | operator that conditions discrete events and
aggregates; see Conditioning.
Introduction
A random-variable column stores, in each row, a token referring to a
probability distribution instead of a single value. The token has type
random_variable (a provenance token, castable to uuid) and fits
in any CREATE TABLE:
CREATE TABLE sensor_readings(
  id      int PRIMARY KEY,
  reading random_variable);

INSERT INTO sensor_readings VALUES
  (1, normal(2.5, 0.5)),
  (2, uniform(1, 3)),
  (3, exponential(0.4));

SELECT add_provenance('sensor_readings');
The add_provenance call is optional. A random_variable
column is already a provenance token, so every query in this chapter –
the comparisons, the moments, the conditioning – works without it.
add_provenance adds a Boolean provenance token for each row, so
tuple-level uncertainty (a row that may or may not be present, see
Probabilities) combines with random-variable events in the same
query.
The remainder of this chapter uses this sensors example as a running motivator. Each row carries a different kind of noise:
sensor
1is a calibrated unit with Gaussian measurement error centred at2.5;sensor
2is a cheap unit whose reading is uniformly distributed between1and3;sensor
3is a drift-prone unit whose reading is exponentially distributed with rate0.4.
Filtering against a numeric threshold makes each row’s presence depend on the event that its reading satisfies the filter:
SELECT id FROM sensor_readings WHERE reading > 2;
-- id 1, 2, 3 selected with respective probabilities
--   1 - Φ((2 - 2.5) / 0.5)  ≈ 0.84   (Normal CDF)
--   (3 - 2) / (3 - 1)       =  0.50   (Uniform CDF)
--   exp(-0.4 · 2)           ≈ 0.45   (Exponential survival)
These probabilities are read with probability over
provenance (see Probabilistic Queries below).
Distribution Constructors
The constructors below each return a random_variable; every call mints a
fresh, independent variable (use mixture when two draws must share
underlying randomness). The tables give each family’s support, what is
computed in closed form, and any closure (sum / product / min stability); the
Reference column links to Wikipedia.
Continuous parametric
Distribution |
Reference |
Support |
Closed form |
Notes |
|---|---|---|---|---|
|
|
moments, CDF, quantiles, truncated moments; sum-closed |
|
|
|
|
all exact |
|
|
|
|
all exact; sum-closed (Erlang) |
mean |
|
|
|
moments, CDF; same-rate sum-closed |
sum of |
|
|
|
moments, CDF (lower incomplete gamma); same-rate sum-closed |
mean |
|
|
|
via gamma |
sugar for |
|
|
|
moments, CDF, quantiles, truncated moments; product-closed |
|
|
|
|
mean, variance, CDF (sigmoid), quantiles |
the logit link; mean |
|
|
|
moments, CDF, quantiles, truncated moments; min-stable |
scale |
|
|
|
moments, CDF, quantiles, truncated moments (any params); min-stable |
heavy tail; divergent moments reported as |
|
|
|
moments, CDF (incomplete beta), truncated moments |
|
|
|
|
moments, CDF (upper incomplete gamma) |
|
|
|
|
moments (all finite), CDF (via |
Brownian first-passage; ratio- |
Discrete parametric
These families are enumerated into a categorical distribution through
categorical_from_log_pmf (also usable directly for a custom
pmf). Moments,
quantiles, and comparisons – including exact = / <> point
masses – are exact over the enumerated support; an infinite support is
truncated at a 1e-15 relative-mass tail, and a support of more than
10000 outcomes raises an error. Degenerate parameters
(poisson(0), binomial(n, 1)…) give an as_random
constant.
Distribution |
Reference |
Support |
Notes |
|---|---|---|---|
|
|
rate |
|
|
|
|
|
|
|
number of trials (support starts at 1) |
|
|
|
failures before the |
|
|
|
draws without replacement |
Nonparametric and structured
Distribution |
Reference |
Support |
Notes |
|---|---|---|---|
|
|
Dirac point mass; also the implicit numeric -> |
|
|
finite |
all exact; |
|
|
union of arms |
|
|
|
|
Gaussian mixture; exact moments and sampling; comparisons ride Monte Carlo |
|
|
sample values |
ecdf via categorical; exact moments/quantiles; <= 10000 distinct |
|
|
|
piecewise-linear CDF; exact moments/sampling; comparisons ride Monte Carlo |
Implicit casts integer → random_variable, numeric →
random_variable and double precision → random_variable
are installed. Writing WHERE reading > 2 works without an
explicit as_random(2) wrapper.
rv_families lists the parameterised families, one row per
family with its name, parameter count and parameter symbols.
Arithmetic on Random Variables
The arithmetic operators +, -, *, /, ^ and unary
- are declared on (random_variable, random_variable) and
return a new random_variable. Mixing scalars and random variables
works through the implicit casts above:
-- All of these are well-typed random_variable expressions.
SELECT reading + 1            FROM sensor_readings;
SELECT 2 * reading - 0.5      FROM sensor_readings;
SELECT -reading               FROM sensor_readings;
SELECT reading ^ 0.25         FROM sensor_readings;
SELECT r1.reading / r2.reading
  FROM sensor_readings r1, sensor_readings r2
 WHERE r1.id < r2.id;
Beyond the operators, the nonlinear transforms pow /
power (function spellings of the ^ operator),
ln, exp, and sqrt (pure sugar for
^ 0.5) apply per draw. A draw outside their domain raises an error
at evaluation time: a negative argument of ln (0 yields
-Infinity), or a negative base under a non-integer exponent (write
pow(greatest(x, 0), p)); integer exponents work for any base.
Moments of a nonlinear transform are estimated by Monte Carlo, except
for exp of a normal and ln of a lognormal, which are exact.
Arithmetic builds an expression without evaluating it; the value is
computed when queried (expected, probability,
rv_sample…), exactly where the shape allows, otherwise by
Monte Carlo (see Exact vs. Sampled Answers below).
Comparison operators <, <=, =, <>, >=, >
on (random_variable, random_variable) have type boolean; in a
query they become probabilistic events (see Probabilistic Queries
below).
Order Statistics: greatest / least, min / max
Order statistics over random variables come in two shapes.
The same-row form takes several random variables and returns their pointwise maximum or minimum:
-- Three independent U(0,1) columns in one row.
CREATE TABLE d AS
  SELECT uniform(0,1) AS x, uniform(0,1) AS y, uniform(0,1) AS z;

SELECT expected(greatest(x, y, z)) FROM d;   -- 0.75  (= 3/4)
SELECT expected(least(x, y, z))    FROM d;   -- 0.25  (= 1/4)
SELECT variance(greatest(x, y, z)) FROM d;   -- 0.0375 (Beta(3,1))
The SQL GREATEST / LEAST syntax accepts random_variable
arguments in queries ProvSQL rewrites; the functions
provsql.greatest(variadic random_variable[]) /
provsql.least(...) do the same and also work outside such queries.
NULL arguments are ignored, as in the built-in.
The aggregate form extends min / max to random variables,
like the sum / avg / product aggregates:
WITH s(r) AS (VALUES (uniform(0,1)), (uniform(0,1)), (uniform(0,1)))
SELECT expected(max(r)), expected(min(r)) FROM s;   -- 0.75, 0.25
A row absent in a world contributes -inf to max and +inf
to min, so it cannot perturb the extremum; an empty group itself
is SQL NULL, as standard SQL MIN / MAX report.
The mean of a maximum or minimum of independent distributions is
computed without sampling (exactly for i.i.d. uniforms or
exponentials); other shapes use Monte Carlo. Ordering or
de-duplicating a random_variable directly (ORDER BY rv,
DISTINCT rv) raises an error pointing at these constructors.
CASE Over Random Variables
A searched CASE whose WHEN guards are random-variable
comparisons and whose branches are random variables is itself a random
variable: in each draw, the value of the first branch whose guard
holds, else the ELSE default:
-- max, written as a CASE (equals greatest(x, y, z))
SELECT expected(CASE WHEN x >= y AND x >= z THEN x
                     WHEN y >= z            THEN y
                     ELSE z END) FROM d;             -- 0.75

-- abs:  E|N(0,1)| = sqrt(2/pi)
SELECT expected(CASE WHEN n >= 0 THEN n ELSE -n END)
  FROM (SELECT normal(0,1) AS n) t;                  -- 0.7979

-- ReLU: E[max(N,0)] = 1/sqrt(2*pi)
SELECT expected(CASE WHEN n >= 0 THEN n ELSE as_random(0) END)
  FROM (SELECT normal(0,1) AS n) t;                  -- 0.3989
Numeric branches must be cast explicitly (ELSE as_random(0) or
ELSE 0::random_variable): PostgreSQL does not apply the implicit
numeric casts to CASE branches. Guards and branches see one
consistent draw, so variables they share stay correlated.
Moments of a CASE are exact for a piecewise-affine function of one
random variable (abs, clamp, ReLU) and for a CASE computing
the max or min of several random variables; other shapes use Monte
Carlo. A CASE passed to a set-returning function (support,
rv_sample) in the FROM clause must be materialised first
(CREATE TABLE ... AS SELECT CASE ...).
Probabilistic Queries
Filter predicates, joins, and unions on random_variable columns are
written as ordinary SQL:
SELECT id, provenance() AS prov
FROM sensor_readings
WHERE reading > 2;
The comparison reading > 2 becomes part of each row’s provenance.
The query returns one row per source row whose random-variable event
is satisfiable; its probability is obtained with:
SELECT id, probability(provenance()) AS p
FROM sensor_readings
WHERE reading > 2;
--  id |    p
-- ----+--------
--   1 | 0.8413
--   2 | 0.5000
--   3 | 0.4493
Comparisons between two random-variable columns work the same way. A
JOIN condition on random-variable columns becomes part of the
joined row’s provenance, and UNION ALL over relations with
random-variable columns combines the source rows’ provenance as for
any tracked table.
A comparison can also be projected: SELECT x > y returns the
event’s token (a uuid), and the probability(<predicate>)
overload computes the probability of an event written in infix form:
SELECT x > y FROM d;                        -- the event uuid
SELECT probability(x > y) FROM d;           -- 0.5
SELECT probability(x > y AND x < z) FROM d; -- 0.1667  (ordering y<x<z)
probability is also a short alias of
probability_evaluate on a uuid; the predicate overload
exists only under the name probability. On a deterministic Boolean
it returns 0 or 1.
Two comparison events can be conditioned with the same | operator
that conditions a random variable (Conditioning): (A) | (B)
reads “A given B” and evaluates the correlation-aware
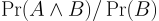 . The result is an event token (a
uuid), usable as a probability argument, a projected
column, or the left operand of a further |:
-- x ~ Normal(1500, 400); {x >= 2000} ⊂ {x >= 1000}
SELECT probability((x >= 2000) | (x >= 1000)) FROM d;  -- 0.1181
Shared variables are taken into account: here
Pr(x >= 2000 ∧ x >= 1000) = Pr(x >= 2000). Comparisons of a single
distribution against constants are exact (through its CDF); correlated
events over composite expressions such as x + y > z need Monte
Carlo.
Configuration of the Monte Carlo Sampler
Two settings control Monte Carlo evaluation. See Configuration Reference for the full configuration reference.
provsql.monte_carlo_seed(default:-1)Seed of the random generator. The default
-1gives non-deterministic sampling. Any other value (including0) is used as a literal seed and makes every Monte Carlo result reproducible across runs, for both discrete and continuous sampling.provsql.rv_mc_samples(default:10000)Sample count used by
expected,variance,moment,rv_histogram, andrv_sampleunder conditioning, when no closed form applies. Set to0to disable Monte Carlo entirely: such calls then raise an error.
The sample count of probability(..., 'monte-carlo', 'n') is
independent: it is the third argument, passed as a string like every
other probability parameter.
Exact vs. Sampled Answers
Wherever the shape of a query allows, ProvSQL answers it exactly, with
no sampling: family-preserving combinations (sums of normals, affine
transforms…), comparisons resolved from a distribution’s CDF or
support, comparisons between two variables of the same family, and the
other cases this chapter marks as exact. Everything else falls back to
Monte Carlo. Setting provsql.rv_mc_samples = 0 makes a query raise
an error when no exact answer is available: this asserts that a query
is answered exactly.
Moments, Quantiles, and Support
Six polymorphic functions compute moments, quantiles, and supports;
they accept random_variable, plain uuid, numeric, and
agg_token inputs (quantile accepts only
random_variable and plain numeric input).
expected(input [, prov [, method [, arguments]]])Expectation
E[input | prov]; for anagg_token, the expectation of the aggregate over the possible worlds. Withoutprov(defaultgate_one()), the unconditional expectation.variance(input [, prov [, method [, arguments]]])Variance
Var[input | prov], in closed form when available, otherwise by Monte Carlo.moment(input, k [, prov [, method [, arguments]]])Raw moment
E[input^k | prov].kmust be a non-negative integer.k = 0returns1;k = 1is equivalent toexpected.central_moment(input, k [, prov [, method [, arguments]]])Central moment
E[(input − E[input | prov])^k | prov].k = 0returns1;k = 1returns0;k = 2is equivalent tovariance.quantile(input, p [, prov])p-quantile (inverse CDF)
F⁻¹(p) = min{x : P(input ≤ x | prov) ≥ p}forp ∈ [0, 1]: medians, percentiles, credible intervals.p = 0/p = 1return the (possibly infinite) support edges. Exact for a bare random variable, including under conditioning on an interval; compound expressions use the Monte Carlo empirical quantile.SELECT quantile(posterior, 0.025) AS lower_95, quantile(posterior, 0.5) AS median, quantile(posterior, 0.975) AS upper_95 FROM model_posteriors WHERE param = 'mu_revenue';
support(input [, prov [, method [, arguments]]])Support interval
[lo, hi], narrowed by the bounds thatprovimposes.
Three further functions take random_variable arguments from the
same row (they are not aggregates over a group of rows):
stddev(x [, prov])Standard deviation
sqrt(Var[x | prov]).covariance(x, y [, prov])Covariance
E[xy | prov] − E[x | prov]·E[y | prov]; exactly0for arguments over disjoint sets of random variables.correlation(x, y [, prov])Pearson correlation;
NULLwhen either argument is constant.
-- shared drift leaf: both sensors move together
SELECT correlation(drift + noise_a, drift + noise_b) FROM s;
Three information-theoretic functions (all in nats):
entropy(x [, prov])Shannon entropy for a discrete distribution, differential entropy for a continuous one; exact for a distribution, estimated by Monte Carlo for arithmetic expressions and under
prov.kl(p, q)Kullback-Leibler divergence
KL(P ‖ Q), exact;InfinitywhenPis not absolutely continuous with respect toQ. Both arguments must be distributions, not arithmetic expressions.mutual_information(x, y)Mutual information
I(x; y): exactly0for arguments over disjoint sets of random variables, otherwise in general estimated by Monte Carlo.
SELECT kl(posterior, prior)           AS information_gain,
       entropy(posterior)             AS residual_uncertainty,
       mutual_information(x, x + eps) AS shared_information
FROM model;
End-to-end on the sensors fixture:
SELECT id,
       expected(reading)   AS mean,
       variance(reading)   AS var,
       support(reading)    AS supp
FROM sensor_readings;
The expectation, variance, and support of normal(2.5,
0.5) come out exactly as 2.5, 0.25, and
(-Infinity, +Infinity); the uniform’s as 2, 1/3, and
(1, 3); the exponential’s as 2.5, 6.25, and
(0, +Infinity).
Independence shortcuts. Sums of independent random variables
have exact expectation and variance, and products of independent
random variables have exact expectation (E[XY] = E[X]·E[Y]);
other shapes use Monte Carlo.
Conditional Inference
The functions above accept an optional prov uuid argument that
conditions the result on the provenance event prov. In a tracked
query, every WHERE filter on a random-variable column is part of
the row’s provenance, so passing the provenance
pseudo-column conditions on the filter:
SELECT id,
       expected(reading, provenance()) AS cond_mean,
       variance(reading, provenance()) AS cond_var
FROM sensor_readings
WHERE reading > 2;
The conditional means are those of the truncated distributions:
≈ 2.64 for the normal, 2.5 for the uniform (now on
[2, 3]), and 2 + 1/0.4 = 4.5 for the exponential.
Conditioning on a one- or two-sided interval is exact for the families
with closed-form truncated moments (Normal, Uniform, Exponential,
Log-normal, Weibull, Pareto, Beta); other shapes are estimated by Monte
Carlo. If the conditioning event is rare, few samples may be accepted,
and a NOTICE suggests increasing provsql.rv_mc_samples.
Sampling and Histograms
Two functions return raw and binned samples.
rv_sample(token, n [, prov])RETURNS SETOF float8Draws
nsamples of the valuetoken, conditioned on the provenance eventprov(unconditional by default). Whentokenis a bare Uniform, Normal, Exponential, Log-normal, Weibull, Pareto or Logistic variable and the event an interval on it, exactlynsamples are returned; otherwiseprovsql.rv_mc_samplesdraws are attempted, and aNOTICEis emitted when fewer thannsatisfy the event.rv_histogram(token, bins [, prov])RETURNS jsonbHistogram of
provsql.rv_mc_samplesdraws of the same value, as a JSON array of{bin_lo, bin_hi, count}objects (binsdefaults to30). A conditionedX | Cgives the histogram of its conditional distribution.
Example, drawing 200 samples from the sensor-1 reading conditioned on
reading > 2.5:
SET provsql.monte_carlo_seed = 42;
SELECT s
FROM (SELECT reading, provenance() AS prov
        FROM sensor_readings
       WHERE id = 1 AND reading > 2.5) q,
     LATERAL rv_sample(q.reading::uuid, 200, q.prov) AS t(s);
Mixtures and Categorical Random Variables
The two overloads of mixture differ in whether the Boolean
coin is shared: a coin given as a provenance token (uuid) makes
several mixtures pick the same side in each draw, while a scalar
probability creates a fresh coin per call:
-- Mint a shared coin: a fresh gate_input token pinned to
-- probability 0.3.
CREATE TEMP TABLE coin(p uuid);
INSERT INTO coin VALUES (public.uuid_generate_v4());
SELECT create_gate((SELECT p FROM coin), 'input');
SELECT set_prob((SELECT p FROM coin), 0.3);

-- Two mixtures coupled through the shared coin: they always
-- pick the same side per Monte-Carlo iteration.
SELECT
  mixture((SELECT p FROM coin),
          normal(0, 1),
          normal(10, 1))   AS shared_a,
  mixture((SELECT p FROM coin),
          uniform(-1, 1),
          uniform(9, 11))  AS shared_b;

-- Two ad-hoc mixtures: each mints its own fresh coin.
SELECT
  mixture(0.3, normal(0, 1),
               normal(10, 1)) AS independent_a,
  mixture(0.3, uniform(-1, 1),
               uniform(9, 11)) AS independent_b;
A categorical assigns explicit probabilities to its
outcomes:
-- 0 with probability 0.2, 1 with probability 0.5, 2 with 0.3
SELECT categorical(
         ARRAY[0.2, 0.5, 0.3]::double precision[],
         ARRAY[0, 1, 2]::double precision[]);
Two categorical(probs, outcomes) calls with the same arrays
produce two independent categorical draws.
Aggregation Over Random Variables
Three aggregates lift the standard arithmetic aggregates from
deterministic scalars to random_variable columns:
sum(random_variable)RETURNS random_variableProvenance-weighted sum
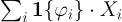 . An empty group
is SQL
NULL(as standard SQLSUM).avg(random_variable)RETURNS random_variableProvenance-weighted average
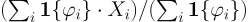 . An empty group is SQL
NULL(as standard SQLAVG).product(random_variable)RETURNS random_variableProvenance-weighted product
 : rows with false provenance
contribute
1. An empty group is SQLNULL, as for the other aggregates.
Note
AVG returns NaN (the floating-point 0/0, not an error)
when every row’s provenance is false. If you need NULL on
such groups, filter by probability(provenance()) > 0
before averaging.
COUNT over a tracked random_variable column counts rows as
for any tracked table.
The SQL statistical aggregates are lifted the same way, each returning
a random_variable over the rows present in each world:
covar_pop, covar_samp, corr,
stddev_pop, stddev_samp, and
percentile_cont (fraction) WITHIN GROUP (ORDER BY
random_variable) (on a tracked table only). A world where the
statistic is undefined (too few rows, zero variance) gives NaN and
is skipped by the moment functions. Their moments are estimated by Monte
Carlo. These aggregates, one value per group of rows, differ from the
same-row readouts covariance / correlation /
stddev above.
Latent variables and posterior inference
A distribution parameter may itself be a random variable (or an
agg_token cast to uuid). The parameter is then a latent
variable and the result a compound (hierarchical) distribution,
for instance a Normal whose mean is drawn from a broad prior:
-- M ~ Normal(0, 10);  X ~ Normal(M, 1):  a hierarchical model.
SELECT expected(normal(normal(0, 10), 1));
All continuous constructors accept a random variable in any parameter
position, except erlang, chi_squared and wald; among the
discrete ones, poisson, geometric, binomial (its
probability) and negative_binomial do (e.g., poisson(120 * R)).
The mean of a compound distribution is exact when the family’s mean is
affine in its parameters (Normal, Uniform, inverse-Gaussian, Poisson);
other moments are estimated by Monte Carlo. A latent shared by
several distributions correlates them: two normal(M, 1) over the
same M are positively correlated.
Note
A drawn parameter outside a family’s domain (a sampled scale or
rate ≤ 0) raises an error. Put a positive-support prior on such
a parameter (e.g., gamma / lognormal).
Posterior inference (likelihood weighting). Conditioning a latent on
an observed value is posterior inference, written as a conditional
equality: X | (Y = c) observes that the distribution Y took
the value c. A single observation is written like truncation
conditioning (Conditioning); for a table of observations, the
prefix | operator (given) produces per-row evidence that
and_agg combines into one evidence token, passed as the
conditioning argument of any function above:
-- Single observation: posterior of mu given normal(mu, 1) = 8.
WITH model AS (SELECT normal(0, 10) AS mu)
SELECT expected(mu | (normal(mu, 1) = 8)) FROM model;

-- A table of observations x_i ~ Normal(mu, 1); posterior mean/variance:
WITH model AS (SELECT normal(0, 10) AS mu)
SELECT expected(mu, ev), variance(mu, ev)
FROM   model,
LATERAL (SELECT and_agg(| (normal(mu, 1) = x)) AS ev
         FROM (VALUES (8.0), (10.0), (12.0)) AS obs(x)) e;
The posterior is computed by importance sampling (latents drawn from
the prior, each draw weighted by the observations’ densities);
equalities and inequalities (Y > c) can be combined in the same
evidence. The posterior predictive is rv_sample on a new
distribution that reuses the latent.
Exact conjugate posteriors. When the latent is a bare distribution and every observation is of a distribution with the latent in one parameter and literal other parameters, forming one of the conjugate pairs below, the posterior is exact, with the same queries:
Observed leaf (latent slot) |
Prior |
Posterior |
|---|---|---|
|
|
Normal (precision-weighted) |
|
|
Normal (update at |
|
|
Gamma |
|
|
Gamma |
|
|
Gamma |
|
|
Beta |
|
|
Beta |
|
|
Beta |
|
|
Pareto |
|
|
Gamma |
Mixed likelihoods sharing one conjugate prior compose (a Gamma-prior rate observed through both Poisson counts and Exponential gaps). Other shapes use importance sampling.
Note
As a WHERE selection, a continuous point event Y = c matches
nothing; only as a conditioning event is it an observation. Y
must be a bare distribution: observing a derived quantity
((X + Y) = d) is not supported, and the observations must share
the latent within one query.
Marginal likelihood and diagnostics. evidence returns the
marginal likelihood P(data). When many observations constrain one
latent, the effective sample size of the importance sampler collapses;
a WARNING is emitted when it falls below
provsql.ess_warn_fraction of the accepted draws: increase
provsql.rv_mc_samples.
Explaining the posterior. shapley_observe returns the
Shapley value of each observation (at most 12) over a posterior moment:
which observation most shifted the posterior. The values sum to the
shift from prior to posterior.
Studio Integration
ProvSQL Studio (ProvSQL Studio) has three Circuit-mode features for continuous distributions:
Distribution profile:
μandσ²with a histogram, a PDF/CDF toggle, per-bar tooltips, and wheel zoom (computed withrv_histogram).Conditioning input: clicking a result cell puts the row’s provenance into the Condition on input, so every subsequent moment, sample or histogram is conditional. Toggle the Conditioned by badge off to get the unconditional answer.
Simplified-circuit rendering: the circuit is shown as simplified under
provsql.simplify_on_load.
Limitations
The following are not supported:
EXCEPTandSELECT DISTINCTon relations that carryrandom_variablecolumns.Where-provenance combined with random variables.
Editing distributions in Studio.